
Multimodal learning enables artificial intelligence to work with more than one type of information at the same time. Instead of analyzing text, images, audio, or video separately, a multimodal system can connect these signals to build a richer representation of a task or situation. This approach is increasingly relevant to computer vision, natural language processing, speech technology, robotics, and modern AI assistants.
The basic idea is straightforward: combine complementary information so a model can make better-informed predictions, retrieve relevant content, answer questions, or generate responses across different formats.
What Is Multimodal Learning?
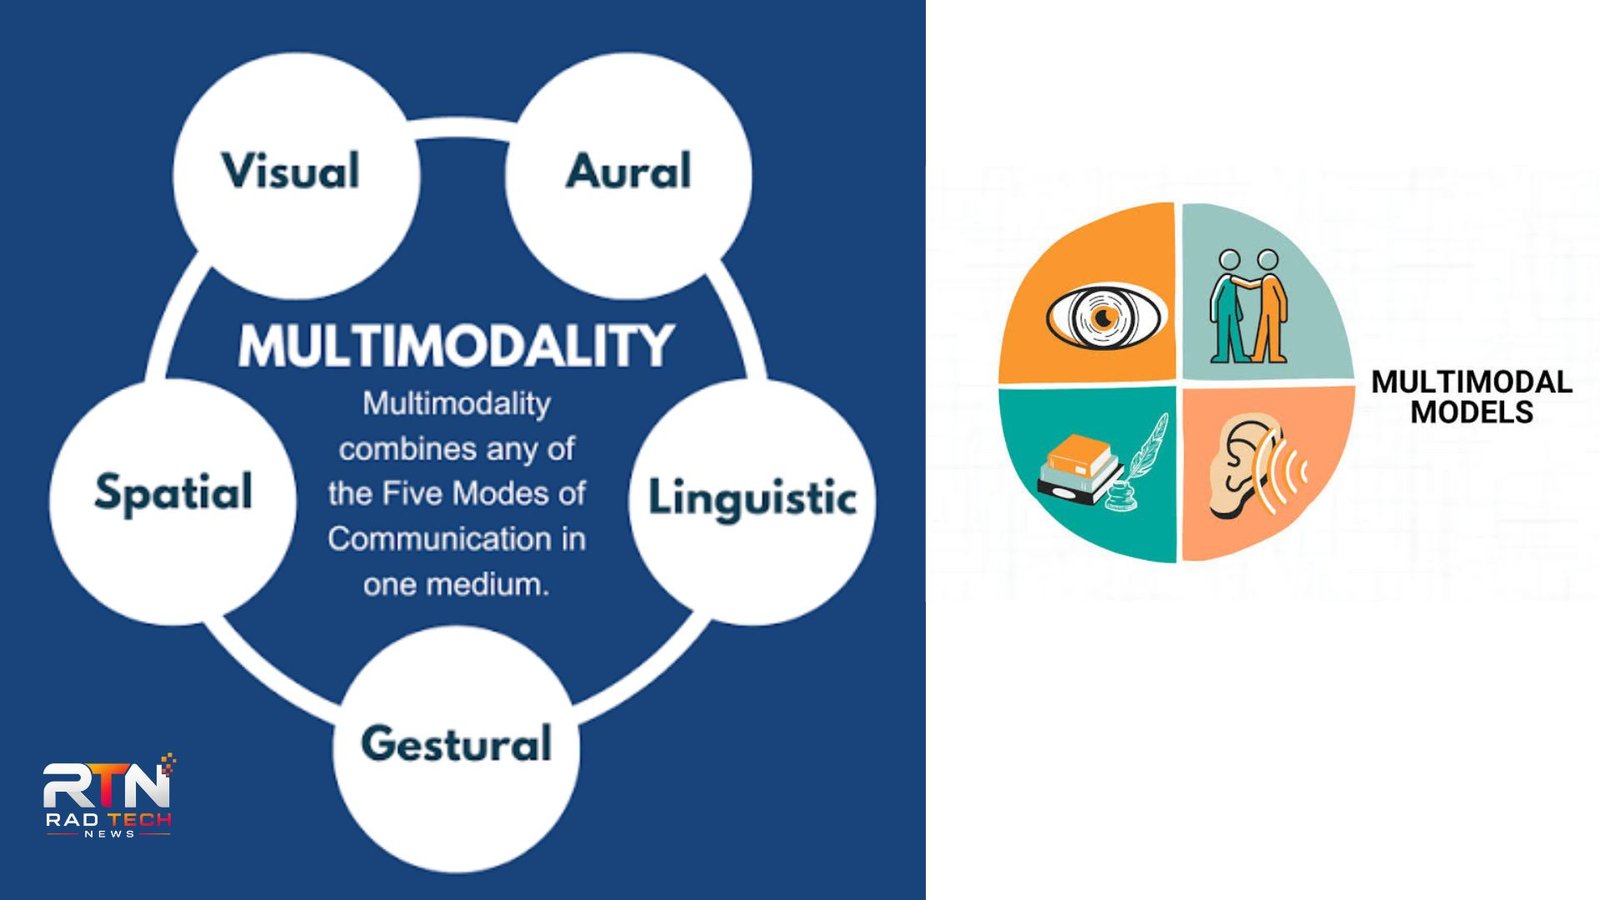
Multimodal learning is a machine learning approach in which a model learns from two or more modalities, such as text and images or speech and video. A modality is simply a distinct form through which information is represented or communicated.
For example, an AI system examining a cooking video could process the spoken instructions, written recipe, objects visible in the frame, and sounds produced during cooking. Each source provides different clues, and their combination can support a more complete interpretation.
Research in multimodal machine learning commonly examines challenges including representation, alignment, translation, fusion, and co-learning.
Common Modalities
Modern systems may work with:
- Text and natural language
- Images and photographs
- Audio and speech
- Video
- Sensor or physiological signals
- Gestures and facial expressions
The exact combination depends on the application and available training data.
How Multimodal Learning Works
A multimodal model generally needs to transform different inputs into representations that can be compared, connected, or processed together.
One common approach is to use separate encoders for different modalities. An image encoder can extract visual features, while a language encoder represents words or sentences. A fusion mechanism can then connect those representations.
Another approach uses a shared architecture that processes several modalities within the same broader model. Transformer-based systems have become particularly influential because attention mechanisms can model relationships between elements from different information sources. Research has explored architectures that combine modality-specific processing with shared representations and cross-modal attention.
The goal is not simply to place different datasets together. The model must learn meaningful relationships between them.
| Approach | How it works | Typical advantage | Main challenge |
|---|---|---|---|
| Early fusion | Combines modality features near the input stage | Can learn direct interactions | Different data formats can be difficult to synchronize |
| Late fusion | Processes modalities separately before combining outputs | Flexible and modular | May miss deeper cross-modal relationships |
| Joint or deep fusion | Learns interactions throughout the network | Stronger cross-modal reasoning potential | Greater computational and training complexity |
Why Multimodal Learning Matters
A single modality can leave important context unexplained. Text may describe an object without showing its appearance, while an image may show an event without explaining what people are saying.
Combining modalities can reduce that information gap.
For example, visual question answering requires a system to connect a question written in natural language with information contained in an image. Video understanding can require simultaneous reasoning about frames, speech, timing, and surrounding context. These tasks illustrate why cross-modal relationships are central to advanced AI systems.
💡 Pro Tip: When evaluating a multimodal system, test whether each modality actually contributes useful information. Adding more inputs does not automatically improve performance; poorly aligned, noisy, or redundant data can make training and evaluation harder.
Applications of Multimodal Learning
The technology has applications across several fields.
AI Assistants and Search
An assistant can interpret a user’s written question alongside an uploaded image, document, chart, or audio recording. This allows queries that would be difficult for a text-only system, such as asking about information contained in a photograph or explaining a visual diagram.
Healthcare and Scientific Research
Multimodal systems can potentially combine different forms of evidence, including written records, medical imagery, signals, and other structured or unstructured information. In scientific settings, researchers can also connect papers, figures, presentations, and recorded explanations. Recent research has specifically examined relationships across scientific text, visuals, and speech.
Education
Educational applications can combine written explanations, diagrams, spoken instruction, and video demonstrations. Such systems may support interactive tutoring, content retrieval, accessibility tools, and analysis of multimedia learning materials.
Robotics and Autonomous Systems
Robots need to interpret information from cameras, microphones, sensors, language instructions, and their physical environment. Multimodal approaches can help connect these signals with actions and task objectives.
Media and Content Creation
Multimodal models can support image captioning, visual question answering, video understanding, cross-modal retrieval, and other tasks involving text, images, and video. Research has demonstrated multimodal models across these task categories.
Benefits and Limitations
The biggest advantage of multimodal learning is contextual understanding. Different modalities can provide complementary evidence, allowing a model to connect information that would otherwise remain isolated.
It can also support more natural human-computer interaction. People routinely communicate through combinations of speech, text, images, gestures, and visual context, so systems capable of processing several of these channels can interact in more flexible ways.
However, the approach introduces substantial challenges. Different modalities have different structures, scales, timing, and levels of reliability. Synchronizing speech with video, for example, is different from aligning an image with a written caption.
Data quality is another concern. Models require suitable multimodal examples and meaningful relationships between inputs. Evaluation can also be difficult because success may depend on perception, reasoning, generation, and cross-modal alignment simultaneously. Current research continues to identify limitations involving fine-grained alignment, task transfer, robustness, efficiency, and safety.
Multimodal Learning vs. Unimodal AI
Traditional unimodal models specialize in one primary data type. A language model may concentrate on text, while a computer vision model focuses on images.
Multimodal learning expands the problem by allowing information from multiple sources to interact. That does not mean multimodal models are automatically superior for every task. A specialized model can remain more appropriate when the problem depends on one modality and demands high efficiency or narrowly focused performance.
The right architecture depends on the task, available data, latency requirements, and desired level of cross-modal reasoning.
📌 Key Takeaway: Multimodal learning is valuable because real-world information rarely arrives in one format. Its effectiveness depends less on simply adding modalities and more on aligning, representing, and combining them in ways that preserve useful relationships.
Frequently Asked Questions
What is an example of multimodal AI?
A vision-language assistant that receives an image and a written question is a simple example. The system must interpret visual information and connect it with language to produce an answer. More advanced applications can incorporate audio, video, documents, and other signals simultaneously.
What are the main types of multimodal data?
Common modalities include text, images, audio, speech, video, gestures, and sensor data. A particular system may combine only two, such as image and text, or several modalities depending on its intended task and training resources.
What is the difference between multimodal and multimodal deep learning?
Multimodal learning is the broader concept of learning from multiple information types. Multimodal deep learning applies deep neural networks to this problem. Modern research includes transformer-based architectures, multimodal pretraining, representation learning, and specialized fusion techniques.
Why is multimodal AI difficult to train?
Different modalities have different formats, timing, resolution, and noise characteristics. Models must learn meaningful correspondences between them while avoiding interference from irrelevant information. Large-scale training can also require substantial computing resources and carefully constructed datasets.
Is multimodal learning the future of AI?
It is an important direction in AI research, particularly for systems that need to understand complex real-world information. Current work spans vision-language models, audio-visual intelligence, multimodal agents, scientific applications, and embodied systems, although significant technical and safety challenges remain.
Conclusion
Multimodal learning gives AI a way to connect information that naturally appears across different formats. By combining language, vision, audio, video, and other signals, models can approach tasks that require richer context than a single data source can provide.
Its long-term value will depend on more than larger models. Better alignment, reliable evaluation, efficient architectures, high-quality datasets, and responsible deployment will be equally important. As multimodal systems mature, their strongest applications are likely to be those where combining distinct forms of evidence genuinely improves understanding or interaction.
